OrbitalHub

Where curiosity reaches escape velocity.

Domain is for sale. $50,000,000.00 USD. Direct any inquiries to contact@orbitalhub.com.

Archive for the Science category


A glowing neural network woven through the open pages of a NASA grant proposal, with the James Webb Space Telescope mirror in soft focus behind it, representing the intersection of peer review and super intelligence in American research


Two days before the second Tuesday in October, the same room at the U.S. Institute of Peace that has hosted peace talks for three decades filled instead with research administrators, lab directors, and the kind of people who can tell you the difference between a Bayesian prior and a proposal deadline. The occasion was the White House Office of Science and Technology Policy’s “Science: A New Golden Age Summit,” convened on October 8, 2026 to translate a July report to the President into a coordinated set of federal science bets. NASA showed up with two of them, and neither one was a new telescope.

The first was a quiet institutional commitment: a coordinated metascience program inside NASA’s Science Mission Directorate, with a permanent expansion of dual-anonymous peer review across the directorate’s research solicitations. The second was a fellowship: ten Genesis Mission Fellows, accelerated doctoral students who will be trained simultaneously in super intelligence and in a traditional NASA mission discipline, and placed inside NASA laboratories to work on real flight programs. Both came wrapped in Isaacman’s framing of a “new Golden Age” but, more usefully, both came with concrete structure: a named review mechanism that already exists, and a fellowship template lifted almost verbatim from a graduate research program that has been running since 2019.

Why does the peer-review expansion matter? The short version is that the agency has been running the experiment for six years and is now extending it. Dual-anonymous peer review, the form NASA Science began piloting in 2020 and folded into the Future Investigators in NASA Earth and Space Science and Technology (FINESST) solicitation in 2024, breaks the link between who writes a proposal and who grades it. Proposers rewrite their science cases to remove identifying details — author names, institution, even the kind of instrument references that flag a specific lab. Reviewers see only the science and the budget. The pilot was launched during the first Trump administration and is, in the agency’s own framing on its Dual Anonymous Peer Review page, a structural response to the cognitive biases Tversky and Kahneman laid out in 1974. The new initiative commits the Science Mission Directorate to expanding that practice further, into more of its Research Opportunities in Space and Earth Sciences (ROSES) programs, and to folding the operational lessons into a coordinated metascience capability that can study its own review outcomes in close to real time.

That is a quieter change than a new flagship, but it lands harder on day-to-day science. ROSES is the pipeline through which the bulk of NASA’s external science gets funded: a single solicitation umbrella that issues dozens of individual program elements each year, ranging from astrophysics theory to Earth-system modeling to heliophysics data analysis. If DAPR is the new default for most ROSES elements, then the median funded investigator — the one whose lab, whose postdocs, and whose instrument pipeline are not famous — is suddenly competing on a more level surface than they were a year ago. The biases that DAPR targets are not exotic. They are the usual ones: prestige-by-institution, halo effects from earlier work, name recognition that follows investigators across subfields. None of these are accusations against individual reviewers. They are properties of a system that puts people in front of proposals and asks them to choose.

The fellowship sits at a different altitude. Genesis Mission Fellows will be doctoral students whose training explicitly couples super intelligence — the federal government’s preferred term for advanced AI systems that can plan and reason across long horizons — with a traditional discipline, the way the original FINESST design already pairs a graduate student with a faculty mentor on a single research question. NASA will support ten such students in the first cohort, working on NASA mission areas at NASA laboratories. The fellowship inherits the bones of FINESST, including its structure as a research grant rather than a traditional fellowship and its $50,000-per-year award size, and bolts on the SI training component. The Department of Energy launched a parallel fellowship structure the same day, aimed at the same kind of dual-competency PhD, with the same general design and a 100-PhD-per-cohort scale, which makes the two programs the first coordinated federal attempt to grow a domestic SI-fluent research workforce rather than rent one from outside.

What makes this a coherent story is the compute underneath it. The White House fact sheet accompanying the announcements lists $2.4 billion in industry commitments to the Genesis Mission Consortium for SI compute and tooling: NVIDIA at $1 billion, AMD at $500 million, OpenAI at $200 million, Anthropic and Google at $150 million each, AMP and Emerald AI at $100 million each, and AWS, Armada, Crusoe, and Micron at $50 million each. That pool is the resource the new fellowships will be trained on, and the resource NASA’s metascience effort will be able to use to study its own review process. It is also the lever that the July expansion of the Genesis Mission pulled: the $5 billion federal commitment that pulled fifteen-plus agencies into the consortium, of which NASA’s two October 8 announcements are the first research-training deliverables.

The engineering question that makes or breaks this is whether the training tracks actually produce researchers who can do original work in their discipline, not researchers who can prompt an SI system about it. The federal design here leans on the rotation model: a doctoral student spends time inside a national lab, time inside an industry partner, and time inside the academic department that granted the degree. The expectation is that the rotation through an industry lab forces the AI work to meet engineering constraints — latency, cost, auditability, integration with real instruments — while the academic time forces it to meet peer-reviewed publication standards. The model is closer to the National Science Foundation’s Graduate Research Fellowships in structure than to anything AI-specific, and that is the point. The novel content is the SI training, not the fellowship scaffolding.

There are real risks. DAPR shifts work onto proposers, who have to rewrite their cases to strip identity, and onto panels, who have to learn to read proposals that read like abstracts. If the rewrite costs more time than the bias reduction saves, the program fails on its own terms. The fellowship, meanwhile, depends on industry partners actually opening their labs to doctoral students, and on academic departments accepting an SI training component that is not yet a recognized subfield. Both are bets about institutional behavior, not just about money.

What changes because of this is the federal science workforce itself. A decade from now, the average NASA principal investigator will be someone who competed for funding under DAPR and probably was reviewed by an anonymous panel rather than a familiar program officer. A cohort of researchers who finished their PhDs with hands-on super-intelligence experience inside a national lab will be the ones writing the next generation of mission proposals. Whether that produces better science depends on details that are still being written into the program’s implementation, but the direction is set. NASA has spent sixty-seven years building tools to look outward. Yesterday it turned two of those tools — peer review and graduate training — on its own house.
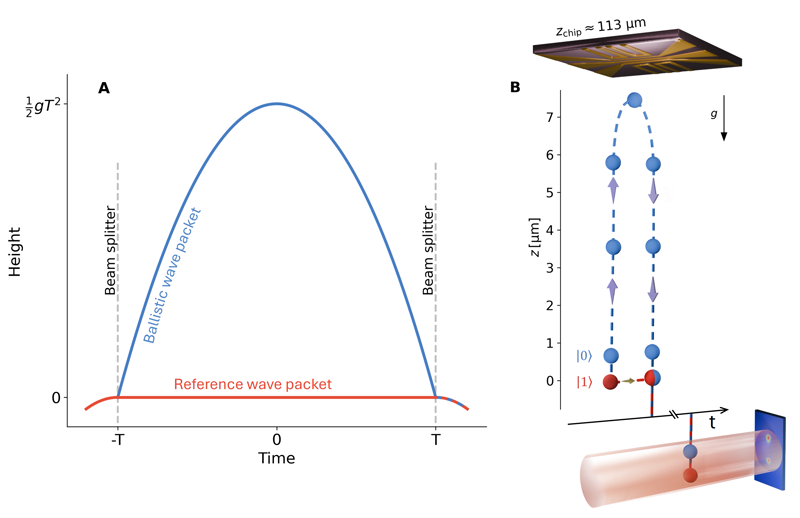


A scientific schematic of the Quantum Galileo Interferometer showing the spacetime trajectories of two wave packets in panel A and the vertical geometry of the atom chip, atom cloud and glass cell in panel B.


In a basement lab at Ben-Gurion University of the Negev, a cloud of about 20,000 rubidium atoms has just answered a question physicists have been asking for nearly a century. Cooled to a few nanokelvin above absolute zero and held still by microscopic wires on a fingernail-sized chip, the atoms were nudged into a quantum superposition in which one half of the cloud rose a few micrometres and fell back under gravity while the other half stayed put. When the two halves were brought back together, the interference pattern between them showed a clean phase shift, and that phase shift matched Einstein’s prediction to within 2.5 percent.

The result, published in Science Advances on 2 September 2026 by Dobkowski, Folman, Penrose, Vedral, Schleich and a dozen other collaborators, is the first direct measurement of the quantum phase accumulated by a freely falling particle. It is also a fresh check on Einstein’s equivalence principle, the assumption that gravity disappears for an observer in free fall. The principle works fine for billiard balls and spacecraft. Until now, no one had checked whether it still works when the falling object is in a quantum superposition of two places at once, which is what the Ben-Gurion group, along with partners at Oxford and Ulm, set out to do. That the check matters at all is because general relativity and quantum mechanics describe the universe with completely different mathematical machinery, and they have resisted every attempt to combine them for almost a century. Most attempts to unify the two assume, implicitly, that the equivalence principle still applies at quantum scales, and this result is the first empirical reason to believe that assumption is correct.

Building the right kind of interferometer took the Folman group years. Ordinary atom interferometers, which have existed since the early 1990s, can compare two paths that both involve motion, one slightly higher than the other or one slightly accelerated with respect to the other. What they cannot do is compare a path that is genuinely free of forces against a path that is held artificially still, which is exactly the situation an equivalence-principle test requires, as Ars Technica reported on 11 September 2026. The team called the new device the Quantum Galileo Interferometer, or QGI, in honour of Galileo’s original observations of free fall, and the underlying method is laid out in detail on arXiv.

Inside a glass cell held under vacuum, a few micrograms of rubidium-87 gas is cooled into a Bose-Einstein condensate, a quantum state in which all the atoms share a single wave function. The condensate floats about 113 micrometres beneath an atom chip, a flat substrate etched with microscopic current-carrying wires that paint the surrounding space with carefully shaped magnetic fields. The chip itself is mounted upside down, with the wires facing the atoms, so the magnetic gradient can levitate the condensate in place. The whole apparatus is small enough to fit on a desk, which is part of why a single lab group could afford to spend years getting it to work, but the measurement it produces has implications for the largest questions in fundamental physics.

The reason it took so long is that interference, the property the experiment depends on, is fragile. Interference only appears when there is no way, even in principle, to tell which path a particle took; any measurement that distinguishes the two paths destroys the quantum superposition and forces the particle to behave like a localised classical object. Wave packets that have fallen under gravity are moving fast, while stationary wave packets are not, and that difference in speed is itself information about the path, so a naive setup would never produce an interference pattern at all. Folman and his colleagues had to design a sequence of pulses that cancels the path information without cancelling the phase information they actually wanted to measure.

Once the atoms are ready, the experiment unfolds in four microwave and magnetic pulses, summarised in Figure 1 of the arXiv preprint. The first pulse puts every atom into a superposition of two spin states: one that feels the magnetic field and one that does not. A magnetic pulse then kicks the magnetically sensitive state upward, launching it on a ballistic arc, while the insensitive state stays put. A second microwave pulse swaps the roles: the rising atom becomes magnetically insensitive and falls freely under gravity, while the stationary atom becomes magnetically sensitive and is held hovering by a field tuned to exactly cancel its weight. A final magnetic pulse acts as a parachute, gently braking the falling atom so it lands back where it started, where the two halves of each atom can interfere. At their farthest apart, the two trajectories were about 7.5 micrometres apart and the longest free-fall time was about two milliseconds. The interference pattern at the end of each run depends on the phase that the falling path accumulated during its trip. The longer the fall, the more phase, and the chirp in those oscillations is the signature the theory predicts. As the team lengthened the fall duration, the measured phase grew in proportion to gT squared, exactly as general relativity predicts for a classical trajectory and as the equivalence principle predicts for a quantum one.

The interpretation is the part that makes the result satisfying rather than just technical. From the perspective of the falling atom, there is no gravity at all: it is in free fall, the way an astronaut is in orbit, and its wave should pick up no extra phase. From the perspective of the laboratory, the same atom is being pulled downward at 9.81 metres per second squared, and its wave should accumulate a phase proportional to gT squared. The two views should agree, and Einstein’s equivalence principle says they do. The QGI measures the lab-frame phase directly and shows that, to within the experiment’s precision, the falling quantum wave accumulates exactly the phase that gravity predicts. As The Brighter Side reported, the measurement is a checkpoint on the boundary between two theories that physicists are still trying to merge. The result does not say which, if either, will eventually have to give way, but it sets a baseline that future versions of the experiment will sharpen.

A first upgrade is already under construction at Ben-Gurion. The next-generation QGI is being designed to put nanodiamonds, particles roughly ten orders of magnitude heavier than rubidium atoms, into the same kind of superposition. Nanodiamonds sit in a mass range where several competing quantum-gravity models and collapse theories make different, falsifiable predictions, and putting a nanodiamond in superposition for any usable time has not yet been achieved. Folman told Ars Technica that his lab is already working on a design that he hopes will let the heavier experiment run within the next four or five years, though he was clear that it is “a very, very challenging project.” If it works, the team would have a direct laboratory test of the boundary between quantum mechanics and gravity in a regime where competing theories actually disagree.

In the meantime, the September result establishes something that has been assumed but not shown. When an atom falls, the quantum phase it picks up is the phase that gravity, applied classically, would predict. The equivalence principle, written down by Einstein in 1907 and tested for classical masses by Galileo, Newton, Bessel and Eötvös, has now been demonstrated, in a single careful experiment, for a particle that is in two places at once. The result does not resolve the long-standing tension between general relativity and quantum mechanics, but it removes one of the most reasonable doubts about how the two might eventually be unified: that the equivalence principle, which is foundational to general relativity, might quietly break at quantum scales. It does not appear to.


An artist's concept of a Type Ia supernova exploding in the intergalactic space between galaxies within a galactic cluster, used by supernova cosmology programs to standardise the brightness of these explosions across cosmic time. Image credit: Alex Parker / NASA / SDSS.


A decade after Type Ia supernovae earned half of the 2011 Nobel Prize in Physics for revealing that the expansion of the universe is accelerating, the same class of explosion is now driving the sharpest empirical challenge yet to the explanation behind that acceleration. In two companion papers posted to arXiv on 2 September 2026, a team led by University of Queensland PhD candidate Ryan Camilleri has stitched together 2,884 Type Ia supernovae drawn from the Pantheon+ and Dark Energy Survey five-year samples into a single, internally consistent compilation called Unite. When Unite is combined with cosmic microwave background and baryon acoustic oscillation data, the best-fit cosmology is no longer one with a constant dark-energy density. It is a flat universe whose dark-energy equation of state evolves with cosmic time, parameterised by today’s value w0 = -0.86 and a running slope wa = -0.60. That combination fits the combined data noticeably better than the cosmological constant, and the second paper reports that the host-galaxy mass corrections that make the sample consistent push the significance for time-evolving dark energy from 3.4 to 4.0 sigma relative to the older Pantheon+ result.

Why this matters is the size of the cosmological constant in the standard model and the conspicuous lack of a physical explanation for it. The standard Lambda-CDM picture of cosmology, described in detail in the Wikipedia dark-energy entry, treats dark energy as a fixed energy density, the cosmological constant, that fills space uniformly and does not change with cosmic time. That assumption has held up against every supernova sample, every galaxy-cluster count, and every CMB map for nearly three decades. It is also the assumption under which the accelerating expansion discovered in 1998 won a Nobel Prize. A growing body of independent probes, including the Dark Energy Spectroscopic Instrument’s measurement of the sound horizon from over six million galaxies and the second data release of the Dark Energy Survey, has begun to show small but coherent deviations from that picture. A w0-wa cosmology, in which the dark-energy density changes with the epoch, was long considered an unlikely complication that would die with more data. The Unite compilation is the first dataset large and internally consistent enough to push that complication past the four-sigma mark by combining supernovae with the CMB and baryon acoustic oscillations, two of the most precise cosmological probes available.

The story behind Unite runs back through the major supernova cosmology programs of the last fifteen years. Pantheon+ is the spectroscopic Hubble diagram assembled by Scolnic and collaborators from the PanSTARRS, Sloan, SNLS, and several earlier samples, totalling roughly 1,500 light curves; it became the workhorse sample for supernova cosmology after the original Pantheon release in 2018. DES-SN5YR is the Dark Energy Survey’s five-year photometric supernova program, which has now grown to be the largest homogeneous sample of Type Ia light curves from a single survey, with around 1,800 light curves of its own. Camilleri’s group combines the two into a single Hubble diagram by reanalysing Pantheon+ with the methodology that DES had already validated on its own data, then running both through the same bias corrections and selection cuts. The combined sample is 2,884 events with a consistent treatment of light-curve shape, colour, and host-galaxy stellar mass, and the team also redetermines host-galaxy stellar masses on a common framework that covers 98% of the sample. The earlier DES analysis of just the DES sample, reported in 2024, had already shown hints of a time-varying dark-energy equation of state. Unite shows the same hint pointing in a slightly different direction, and at a stronger significance when combined with the other probes. As Tamara Davis, the University of Queensland professor who oversaw the work, put it, two independent measurements now point in the same direction, which is what one looks for when the standard model starts to creak.

The deep dive into why supernova systematics matter so much centres on the host-galaxy mass step. Once a Type Ia supernova’s light curve has been standardised by its shape and colour, its peak brightness still depends, at the level of a few hundredths of a magnitude, on the stellar mass of the galaxy that hosted it. Brighter supernovae prefer galaxies with younger stellar populations, while fainter ones tend to land in older, more massive hosts. If that dependence is ignored, the standardised brightness comes out wrong, and the cosmological fit drifts. Earlier work by Vincenzi and collaborators compared the host-mass estimates used in Pantheon+ and DES-SN5YR, and showed that the choice of host-mass measurement alone contributes enough to the standardised magnitudes to flip the supernova-vs-CMB tension on or off. Lee and colleagues re-measure host masses for almost every supernova in Unite using aperture photometry and SED fitting on a single framework. Their masses differ from the values Pantheon+ released, partly because of a redshift-dependent internal inconsistency inside Pantheon+ that the new measurements expose. When the Pantheon+ subset of Unite is combined with baryon acoustic oscillations and the CMB, swapping in the new masses moves the significance for evolving dark energy from 3.4 sigma to 4.0 sigma. The same pair of papers also incorporates gravitational lensing magnification corrections, which slightly blur the standardisation but do not erase the deviation from a constant dark-energy density.

The combination itself is now decisive in a way that earlier work was not. For a flat universe with a constant equation of state, the SN-only fit returns a matter density of Omega_m = 0.310, very close to the standard value. For a flat universe in which the dark-energy equation of state evolves linearly with redshift (the so-called CPL parameterisation), the combined fit to supernovae, the CMB, and BAO returns Omega_m = 0.305, w0 = -0.86, and wa = -0.60, with a dark-energy figure of merit of 315. That value of w0 is less than -1, which means the dark-energy density was higher in the past than it is today. Wa is also negative, which means the dark-energy density is falling faster than the cosmological constant would imply. The combined dataset prefers this picture at the four-sigma level, and the paper’s own figure of merit shows a roughly 30% reduction in the w0-wa confidence region compared with Pantheon+ alone.

The takeaway is that the supernova case for evolving dark energy is now strong enough to be taken seriously, and the question is what kind of evolving. A dark-energy density that decreases with cosmic time is not the same as modified gravity, a quintessence field, or any of the more exotic options the literature considers, but it is no longer the cosmological constant either. The two independent DESI and supernova measurements, one based on sound waves in the early universe and one based on the brightness of stellar explosions in the late universe, now agree on the direction of the deviation, and the supernova side has just gotten both bigger and more internally consistent. The next year or two of data, from the still-pending third year of DES-SN5YR and from the rest of DESI’s first five-year BAO program, will tell whether the deviation grows or shrinks. If it grows, the 2011 textbook picture of dark energy is going to need a rewrite.


Cross-section rendering of the LUX-ZEPLIN time projection chamber: a titanium cylinder of liquid xenon watched by hundreds of photomultiplier tubes, nested inside water and gadolinium-loaded scintillator shielding, deep below the Black Hills of South Dakota. A single bright scintillation flash marks the candidate event in the central fiducial volume.


On June 16, 2023, a single light pulse appeared inside a vat of liquid xenon buried 1,480 meters below the Black Hills of South Dakota. Most flashes like it are noise: stray gamma rays, the occasional neutron, the radioactive decay of trace contaminants in the detector’s titanium walls. This one, recorded in the LUX-ZEPLIN detector at the Sanford Underground Research Facility, did not fit those explanations. By the time the collaboration finished analyzing the data and presented it at the TeV Particle Astrophysics conference in Japan on September 1, the event had become the most credible WIMP dark matter candidate any direct-detection experiment has recorded in a decade (Berkeley Lab, 1 September 2026).

That framing, for the careful reader, does the work. “Most credible” is not “discovery.” The single event sits at 2.6 sigma, where 5 sigma is the threshold physicists treat as a confirmed observation. The probability that background processes alone could produce such a flash is roughly one in two hundred, tantalizing, but not the kind of number on which you write a Nobel citation. The collaboration knows this. Rick Gaitskell, the Brown University physicist who serves as LZ’s spokesperson, called the event “something interesting” and made clear that more data is the only path to certainty (Berkeley Lab, 1 September 2026).

What makes the signal worth talking about is the experiment itself, and what it takes to eliminate every other explanation. The LZ detector holds ten tonnes of liquid xenon kept near 178 kelvin inside a titanium cryostat, nested inside an outer cryostat, surrounded by 17,000 gallons of water in a tank the size of a small swimming pool, wrapped in gadolinium-loaded liquid scintillator, and lodged beneath a mile of Homestake Mine rock (LUX-ZEPLIN Collaboration, NIM A 2020). A WIMP, if WIMPs exist, would interact with the xenon nucleus perhaps once per tonne per year. Everything else has to be ruled out, photon by photon, neutron by neutron.

The story of how dark matter became a question starts almost a century ago. In 1933, Fritz Zwicky applied the virial theorem to the Coma Cluster and concluded that the visible galaxies could not possibly account for the cluster’s rotational behavior; he called the missing mass “dunkle Materie” (Zwicky, Helvetica Physica Acta 1933). Forty years later, Vera Rubin’s spectra of the Andromeda galaxy showed stars in the outer disk moving at the same speeds as those near the center, the rotation curves that have since been measured for thousands of spiral galaxies and remain the cleanest gravitational evidence for unseen mass (Rubin & Ford, ApJ 1970). In 2006, observations of the Bullet Cluster sharpened the argument: during the collision of two galaxy clusters, the X-ray emitting gas decelerated while the gravitational lensing signal passed straight through, implying that most of the mass is in some non-luminous, non-baryonic form (Clowe et al., ApJ 2006).

If dark matter is real, it must be made of something. The leading family of candidates for forty years has been WIMPs, weakly interacting massive particles with masses in the GeV-to-TeV range, predicted independently by supersymmetry and by simple thermal-relic calculations. The relic density is Ω_chi * h² ≈ 0.1, and a coupling near the weak scale gives roughly the right answer, the so-called “WIMP miracle.” None of the direct-detection experiments built to test this prediction has produced a confirmed signal (LZ Collaboration, PRL 2023). Until June 16, 2023.

The LZ detector works because xenon has two properties that are nearly ideal for this kind of search. Its nucleus is heavy, atomic mass 131 on average across xenon’s nine stable isotopes, so a WIMP recoiling off it transfers more momentum than it would off a lighter target. When a particle scatters in liquid xenon, the interaction produces two distinct signals the experiment can read separately: a prompt flash of scintillation light called S1 and a delayed pulse of electrons liberated by the ionization, drifted upward through the liquid into a gas layer where they produce electroluminescence, called S2.

The ratio of S2 to S1 is the discriminator. Electromagnetic interactions, the gammas, betas, and Compton scatters that constitute the bulk of background, produce dense ionization tracks with relatively modest S1, yielding a low S2/S1 ratio. A nuclear recoil, the kind a WIMP would produce if it kicked a xenon nucleus, generates denser ionization per unit of scintillation and a much higher ratio. Plotting S1 against log(S2/S1) and overlaying the two populations gives two well-separated bands. Anything that lands above the electron-recoil band and inside the nuclear-recoil region is, by construction, a candidate.

To get the bands that clean, LZ has to throw out most of its own data. The xenon sits in a titanium time projection chamber about 1.5 meters in diameter and height, with seven tonnes of active liquid in the central volume and roughly 5.6 tonnes kept as the inner fiducial mass. Only events in the fiducial volume are kept; events near the walls are rejected because the dense walls themselves are the largest source of external gamma radiation (LZ Collaboration, NIM A 2020). The chamber is watched by 494 three-inch photomultiplier tubes arranged top and bottom, reconstructing event position to within millimeters. The water tank outside the cryostat is instrumented with 120 PMTs that flag any cosmic-ray muon that might have made it through the rock; the gadolinium-loaded scintillator absorbs neutrons, the most dangerous background because they produce exactly the same S2/S1 signature as a WIMP. The collaboration estimates that the detector now sees about one event per year in the search region from known backgrounds, and on June 16, 2023, it saw exactly one.

The new analysis, led by Sam Eriksen of the University of Bristol, looked at 220 live days of data collected between March 2023 and April 2024, but went further than previous LZ searches. Where earlier analyses looked for the simplest spin-independent WIMP-nucleus coupling, Eriksen’s group widened the energy window to catch interactions that deposit more energy in the detector. The single event was in that high-energy tail (Berkeley Lab, 1 September 2026).

What does the signal imply, if it is real? The collaboration’s best fit suggests a WIMP with mass at least 200 GeV/c², heavier than 200 protons, and a coupling to ordinary matter that is not the simplest spin-independent contact interaction but something more structured. The team has not yet published a cross-section limit curve; that comes when the paper appears on arXiv and is submitted to Physical Review Letters.

The next move is statistical. LZ is still running at SURF and continues to accumulate data; a second event at similar energy would push the significance up sharply, while a long absence would let the signal fade. The competition is also still running. XENONnT at Gran Sasso in Italy uses a similar liquid xenon TPC; PandaX-4T at the China Jinping Underground Laboratory uses four tonnes; both have published null results as of 2025 but are taking more data. The global direct-detection community will, over the next two years, accumulate enough xenon-years to test the same mass range LZ has begun to probe. If the June event was a WIMP, one of the others will see one too.

Two thousand and twenty-six has already been a year for hints. Dark matter remains the largest single thing we cannot name. LZ has spent four years underground doing the slow patient work of elimination. It has built a machine that produces, on average, one spurious-looking event per year. It recorded one.


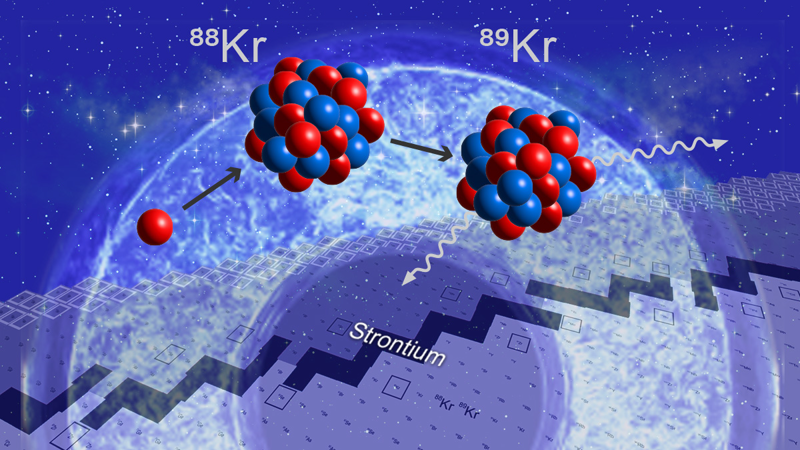
Stylized illustration of the krypton-88 neutron-capture reaction: a free neutron (single red sphere) joins a krypton-88 nucleus (the larger red-and-blue cluster on the left) to form krypton-89 (the cluster on the right), which then emits gamma rays (the wavy arrows). The word "Strontium" sits below on a faint periodic-table strip, with krypton and strontium positions highlighted.


Astronomers who study the oldest stars in the Milky Way spend a lot of time reading chemical barcodes. When those stars formed, the universe had not yet built up much beyond hydrogen, helium, and a thin seasoning of lithium, so almost every heavier element in their atmospheres had to be made inside an earlier generation of stars and then scattered. The relative amounts of those elements tell you which stellar process actually did the forging, and one element in particular, strontium, has refused to behave. New measurements of a nuclear reaction on a related element, krypton-88, now narrow the gap between what the models predict and what the oldest stars show, and the result, published in Communications Physics on 8 June 2026 by Caley Harris, Artemis Spyrou, and a team of collaborators from twelve institutions in the United States, Canada, and Europe, was carried out at the Facility for Rare Isotope Beams (FRIB) at Michigan State University and the ATLAS accelerator at Argonne National Laboratory (FRIB newsroom; Nature paper). What made the experiment possible was a workaround for one of the hardest problems in nuclear astrophysics: most of the reactions that matter for stellar chemistry happen too rarely, and on too short-lived an isotope, to fire a beam straight at a target and count the products. The team measured a different isotope instead and worked backwards.

Why strontium is interesting starts with the fact that the periodic table heavier than iron cannot be built by normal stellar burning. Iron sits at the bottom of the curve of binding energy per nucleon, so fusing more nuclei releases less energy than it costs, and stellar cores cannot climb back up that hill. The solution, laid out in a famous 1957 review by Burbidge, Burbidge, Fowler, and Hoyle, was neutron capture. If a stellar environment can flood a seed nucleus with neutrons fast enough, the nucleus swallows them one at a time and walks up the chart before it has time to beta-decay. That framework identified two regimes: the slow neutron-capture process, or s-process, which works at relatively low neutron densities on long timescales, and the rapid neutron-capture process, or r-process, which runs at extreme neutron densities during, for example, neutron star mergers. Together, those two accounted for nearly everything heavier than iron. By the 1990s, however, surveys of metal-poor halo stars started turning up abundance patterns that neither the s-process nor the r-process could reproduce. Some of those stars had roughly solar amounts of strontium, yet barely any of the heavier elements that should have come along with it under either classical process. In between the two regimes sits a third option, the intermediate neutron-capture process, or i-process, with neutron densities around 10^13 to 10^15 neutrons per cubic centimeter and timescales measured in minutes rather than years. i-process models explain many of these strange patterns, but they consistently come up short on strontium, by factors of several, compared to what the old stars actually show, and modelers had flagged one specific reaction, the neutron capture on krypton-88, as the largest single uncertainty.

The team installed FRIB’s Summing NaI detector, called SuN, at the ATLAS facility to make that measurement. They fired a beam at a target to produce krypton-89, which is krypton-88 with one extra neutron glued on, then watched the gamma rays that krypton-89 emits as it relaxes. Those gamma-ray energies and intensities carry information about the structure of the nucleus and, crucially, about how readily krypton-88 would absorb a neutron in the first place. It is the same logic doctors use when they infer blood chemistry from a downstream signal rather than a direct needle stick: the measurement is indirect, but the inference is solid if the underlying physics is well understood. The result was not what theory had predicted. The measured krypton-88 neutron-capture rate came in consistently lower than the values most nuclear-theory calculations had been using, in some temperature regimes by nearly an order of magnitude. In parallel, the team’s reaction-rate uncertainty dropped from at least a factor of eight down to about a factor of three, which is still wide but no longer the dominant term in the strontium calculation. When the team plugged the new rate into three different i-process models, all of them produced more strontium than before, and the agreement with the stellar observations improved in every case.

The deeper question is what is happening inside the krypton-88 nucleus to slow down the neutron capture. Neutron-capture cross sections depend on the density and spacing of the nuclear energy levels just above the neutron separation energy. If those levels happen to be sparse or have the wrong parity, the incoming neutron has a hard time finding a resonance to grab onto, and the reaction rate drops. Direct measurements are impossible because krypton-88 itself is unstable, so the team turned to its more stable neighbor krypton-89 and used the Oslo method, a well-established technique that extracts level densities and gamma-ray strength functions from a single set of gamma-ray spectra. The SuN detector’s whole purpose is to capture those spectra efficiently; ATLAS provides a clean krypton-89 beam; together the two facilities make the indirect measurement practical. The takeaway is that nuclear structure details in one isotope can shift stellar predictions by a factor of two or more, and the only way to know which way the shift goes is to measure.

It is worth pausing on why strontium specifically shows up so much in this story. Strontium is the lightest element whose production has historically been a clean observational test of which neutron-capture process was active. Heavier elements like barium or lead have so many overlapping production paths that the signatures blur, but strontium sits near the edge of the s-process distribution and far from the r-process peak, so its abundance is sensitive to whatever process is producing the seeds in the middle neutron-density regime. Old stars with strong carbon and slow-neutron features but unusual strontium-to-barium ratios are exactly the kind of objects the i-process was invented to explain, and the FRIB result is the first time an experiment has directly tested the nuclear physics input rather than relying on theoretical estimates. What happens next is mostly back in the hands of the modelers, as Falk Herwig, a co-author at the University of Victoria, framed it in the press release: with the main nuclear uncertainty addressed, the i-process community can turn to the astrophysics, the neutron densities, the timing of the burning episodes inside candidate stars, and the conditions needed to match what the oldest stars actually show. Candidate i-process sites include very low-metallicity asymptotic giant branch stars, post-AGB stars, rapidly accreting white dwarfs, and the helium core flash in low-mass stars, and the new measurement gives all of them a more honest set of inputs to work with. The paper does not claim to have closed the strontium question, only to have removed the single largest nuclear physics unknown behind it. The remaining gap is astrophysical, and that is what the field will spend the next several years tightening.


A glowing DNA double helix unfurling into a grid of single-letter variant predictions, with genome browser tracks for splicing, expression, and chromatin at the base


For a patient whose genome has just been sequenced, the diagnostic question usually is not whether a strange variant exists. There will be dozens. The question is which one of them is making them sick. On 8 September 2026, Google DeepMind released AlphaGenome Atlas, a one-petabyte, nine-billion-row table that aims to make that triage a single look-up instead of a multi-month investigation. It is the largest precomputed biological dataset the company has ever released, more than thirty times the size of the AlphaFold Protein Structure Database at launch (DeepMind, 2026), and it covers the 98 percent of the human genome that does not code for proteins at all.

What the team has done is straightforward to describe and almost absurd in its engineering ambition: take the AlphaGenome sequence-to-function model they published in Nature in January 2026, run it across every possible single-letter substitution at every one of the roughly three billion positions of the human reference genome, store the predictions, and serve them on the open web. Every variant. In advance. With feature attributions attached. With a single composite score, the AlphaGenome Variant Impact (AVI), that collapses the predictions into a number clinical researchers can rank variants by. The bottleneck in human genetics, in other words, has just moved.

To see why this matters, it helps to remember where the field stood a decade ago. In the early 2010s, the human genome was widely described as 98 percent “junk DNA.” That framing did not survive contact with ENCODE, the Roadmap Epigenomics Project, GTEx, or any of the consortium-scale projects that mapped chromatin accessibility, transcription factor binding, histone modifications, and three-dimensional genome contacts across hundreds of cell types. By the early 2020s the consensus was unambiguous: most of the variants statistically associated with common traits and many rare diseases live outside coding exons, in regulatory regions whose effect on the organism can only be inferred by reading the sequence around them and computing what those regions should be doing (Nature, Avsec et al., 2026). The Human Cell Atlas, the 4D Nucleome, FANTOM5 — they produced the data. Predicting the effect of any given mutation on gene expression, splicing, or chromatin, on demand, was the missing piece.

DeepMind’s path to Atlas runs through three increasingly ambitious releases. AlphaFold, in 2020, solved the decades-old protein folding problem and earned Demis Hassabis and John Jumper a share of the 2024 Nobel Prize in Chemistry (Nobel Foundation, 2024). AlphaMissense, in 2023, classified all 71 million possible missense variants in the protein-coding part of the genome as likely benign or pathogenic. Both tools covered only the 2 percent that codes for proteins. AlphaGenome, first released for non-commercial research in June 2025 and described in Nature in January 2026, covers the other 98 percent. Atlas is the precomputed, freely searchable version of that model (DeepMind, 2026; Avsec et al., Nature, 2026).

The early-access users announced alongside the release illustrate what shifts when the bottleneck moves. Laura Covill and Anne O’Donnell-Luria at the Broad Institute used the AVI score to reprioritise a variant in DNM1, a gene strongly linked to epileptic encephalopathy, that had been overlooked in earlier analyses; AlphaGenome predicted an abnormal splice site extending the resulting protein, a mechanism subsequently confirmed by laboratory experiments (DeepMind, 2026). Gareth Hawkes, an MRC fellow at the University of Exeter, ran the Atlas over whole-genome data from more than 54,000 UK Biobank participants and reported 22 percent more non-coding genetic associations than prior pipelines surfaced, including regulatory variants affecting PLA2G7 and EGLN1 and nineteen new regions linked to body mass index. At the Stowers Institute, Julia Zeitlinger and Melanie Weilert used the database to separate transcription factors by their regulatory effects on chromatin, a problem that has resisted biochemical characterisation for two decades.

The architecture behind those results is what makes the engineering tractable. AlphaGenome uses a U-Net-style neural network: an encoder that compresses one million base pairs of input DNA into a dense representation, a stack of transformer blocks that pass information between distant regulatory elements across that window, and a decoder that reconstructs base-pair-resolution predictions across eleven molecular modalities — gene expression, RNA splicing, chromatin accessibility, histone modification, transcription factor binding, three-dimensional contacts, and others — for hundreds of human and mouse cell types (Avsec et al., Nature, 2026). The model was pre-trained on 256 Google TPUv3 chips working in parallel over data from ENCODE, GTEx, the 4D Nucleome, and FANTOM5, and then distilled into a smaller student model that completes the full all-modality, all-cell-type prediction for a single variant in under one second on a single NVIDIA H100 GPU. DeepMind’s genomics lead Žiga Avsec told reporters the team needed an 80-fold speedup over their initial pipeline to make Atlas feasible; they reached it through a combination of model distillation, GPU kernel optimisation, and aggressive elimination of redundant computation (DeepMind, 2026).

The AVI score itself is what lets researchers act on those predictions. It folds the eleven AlphaGenome modalities together with AlphaMissense’s protein-impact estimates and an evolutionary-conservation signal into a single number. On solved rare-disease cases from the GREGoR Consortium, the score placed the known causal variant in the top fifty candidates 29.5 percent of the time; CADD, the most widely used genome-wide variant scoring system in clinical genomics today, managed 12.5 percent on the same benchmark — a 2.4-fold improvement on the metric that matters most to a clinician staring at a patient’s exome (DeepMind, 2026). Each AVI score is paired with feature attributions that say which modality is doing the heavy lifting for any given variant, so a researcher can see not just that a mutation looks bad but why it looks bad.

What changes now is the geometry of the work. Before Atlas, a clinical genomics group that wanted to score a list of candidate variants had to either run a model themselves, rent the compute, or wait on a collaborator who could. After Atlas, they open a browser, type a chromosome coordinate, and read off the score. The cost has collapsed from days of GPU time and a real infrastructure bill to a single API call. The companion AlphaGenome Variant Impact score is freely available through a web portal and API for non-commercial research now, with commercial availability on Google Cloud slated to follow. DeepMind is explicit that the output is not approved for clinical use, and independent reviewers have flagged the obvious limits: many diseases involve multiple interacting variants rather than a single mutation, and some enhancers act over distances longer than the one-million-base-pair window AlphaGenome examines, so their effects fall outside what the model can see (NeoScienceHub, 2026).

The next twenty years of precision medicine will be shaped less by any single sequencing technology than by how quickly reference databases like this one become the substrate that all downstream tools assume exists. AlphaFold did that for structural biology between 2021 and 2025: a problem that used to take a graduate student a year collapsed into something a high schooler could look up. AlphaGenome Atlas has now attempted the same move for the rest of the genome. Whether it actually accelerates diagnoses and mechanism discovery at scale will not be settled in the press release; it will be settled in the next five years of clinical genetics journals, where the question of how often a researcher who never had to run the model themselves first ends up reading the right page of the answer.